
LLM API Pricing in 2026: What a Voice Agent Call Costs
LLM API pricing for voice agents, worked through one 5-minute phone call: the prompt re-sent every turn, the token count line by line, the call priced on Claude, Gemini, Grok, Qwen and OpenAI models, when caching applies, and how the LLM line compares with speech-to-text and voice.
Read the full guide →Deep Dives in This Series
Gemini Live API Pricing in 2026: Cost per Call Minute
Gemini Live API pricing for voice agents, covering Google's audio token rates, why every turn re-bills the whole session, a 5-minute example call priced line by line, and how to keep a long call's cost flat.
Gemini API Pricing in 2026: What a Voice Agent Call Costs
Gemini API pricing for voice agents: Google's list prices for each current Gemini model, one 5-minute phone call priced on each, why implicit caching misses a short phone prompt, the dated price steps and model routing to plan for, and how to switch Gemini models per agent in Dograh.
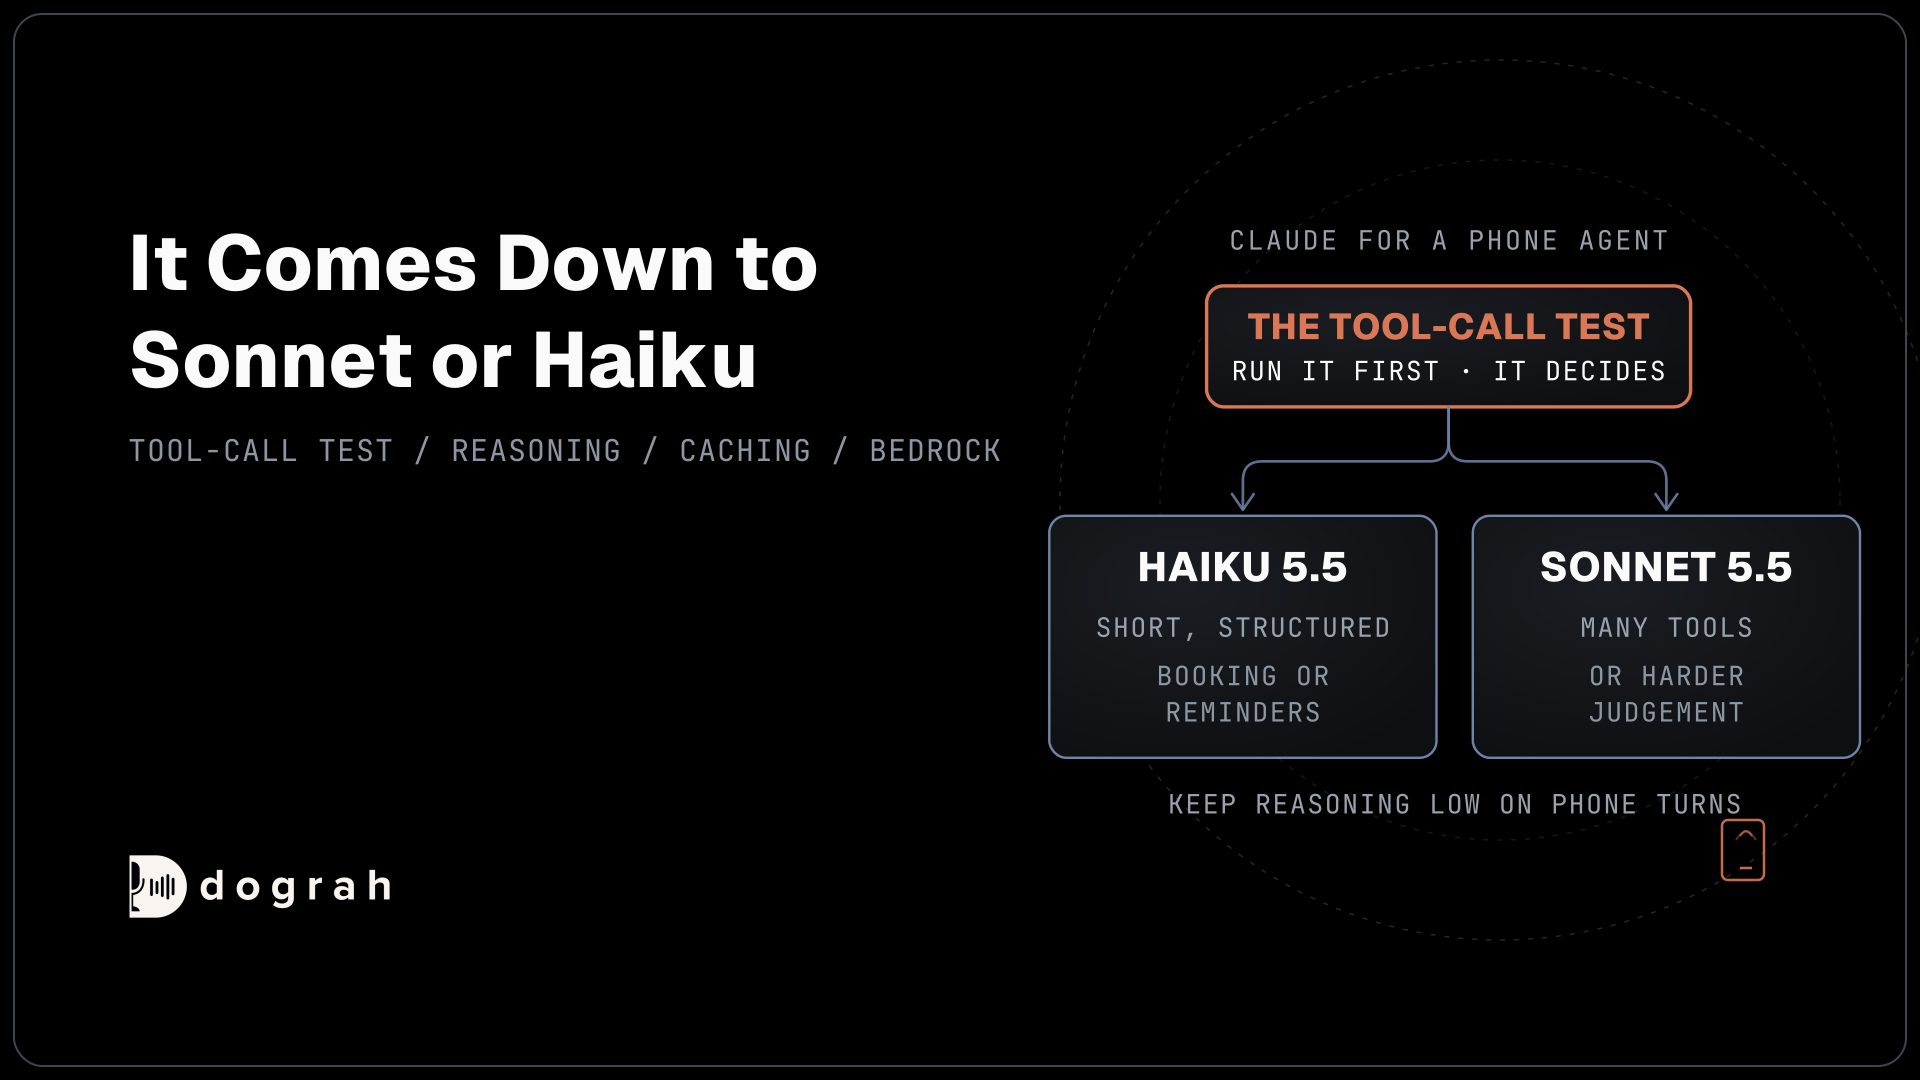
Claude API Pricing in 2026: What a Voice Agent Call Costs
Claude API pricing for voice agents: Anthropic's list prices for every current Claude model, one 5-minute phone call priced on each with the newer tokenizer counted, what prompt caching saves, which model answers fast enough for a phone turn, and how Claude runs in Dograh.
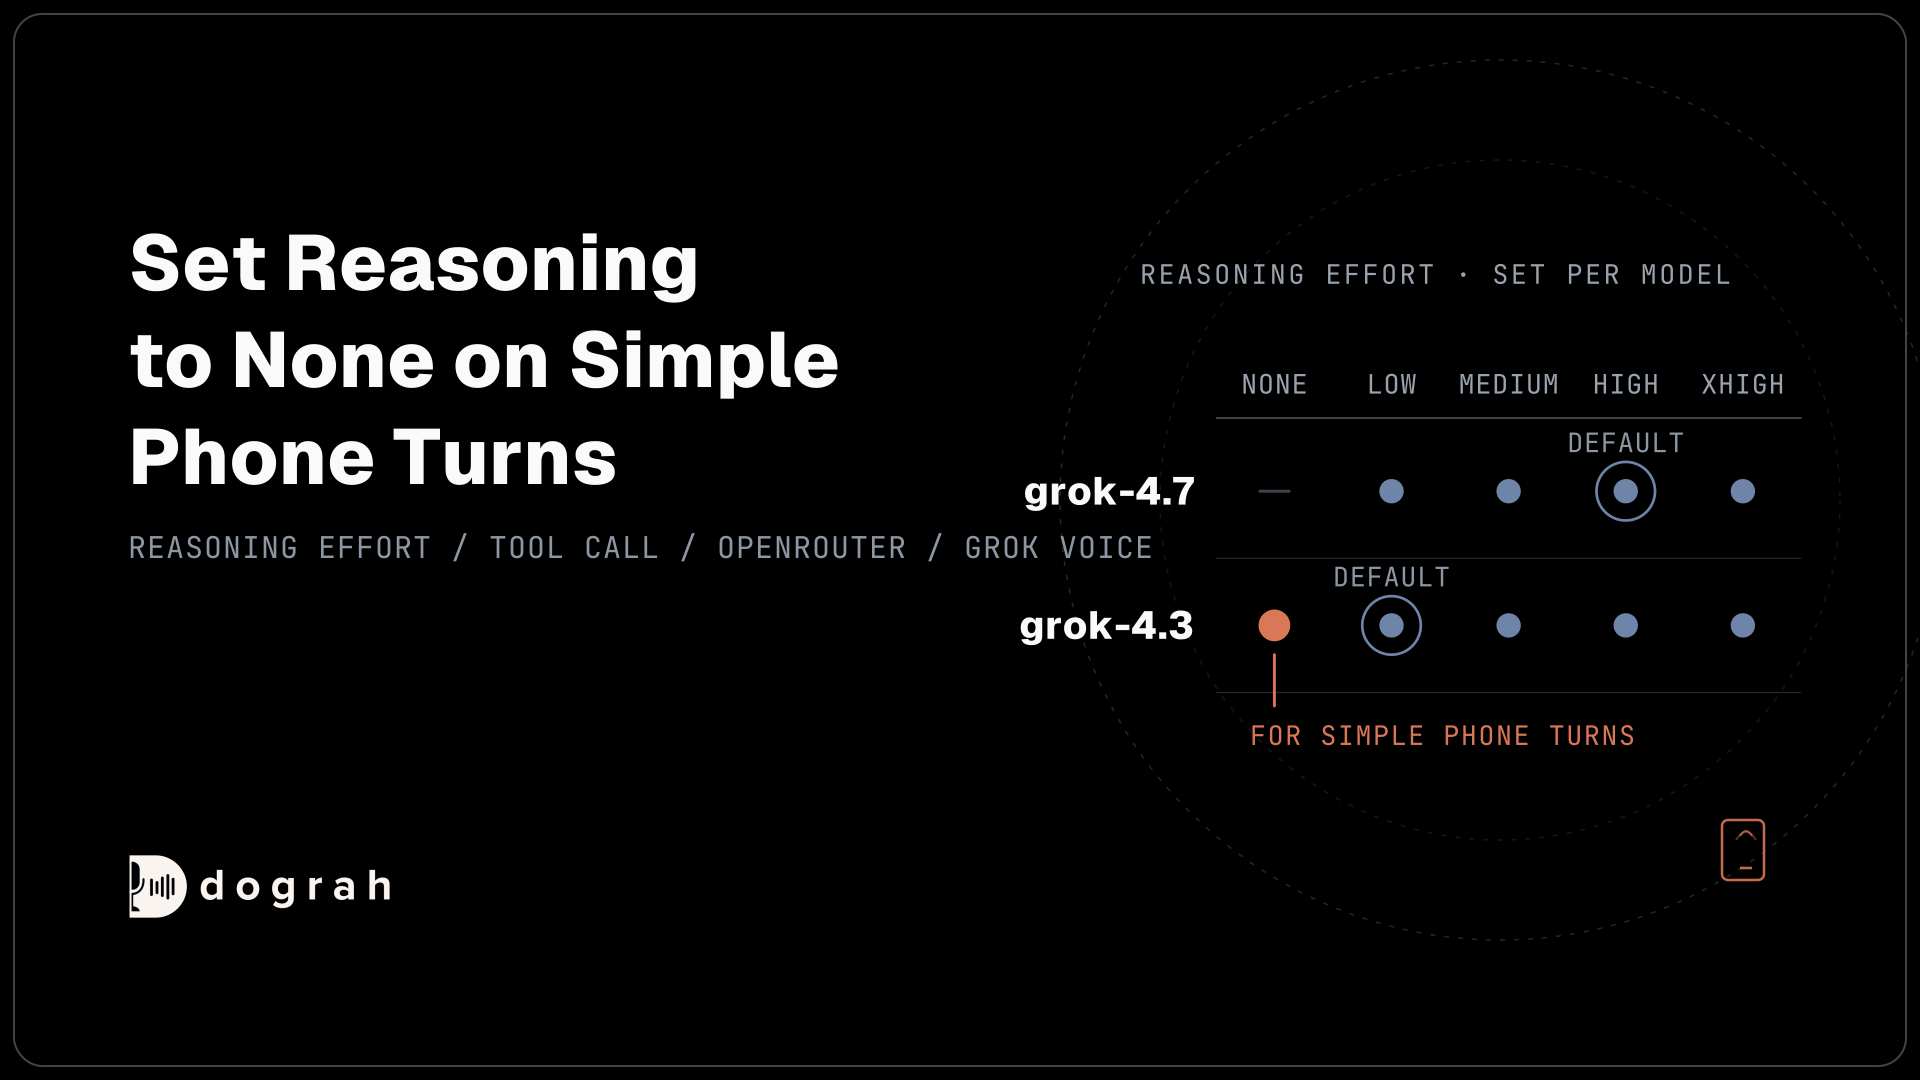
Grok API Pricing in 2026: What a Voice Agent Call Costs
Grok API pricing for voice agents: xAI's list prices for each Grok model, one 5-minute phone call priced on each, what reasoning adds to the bill and the wait, when grok-4.3 with reasoning off is enough, and how Grok runs in Dograh.
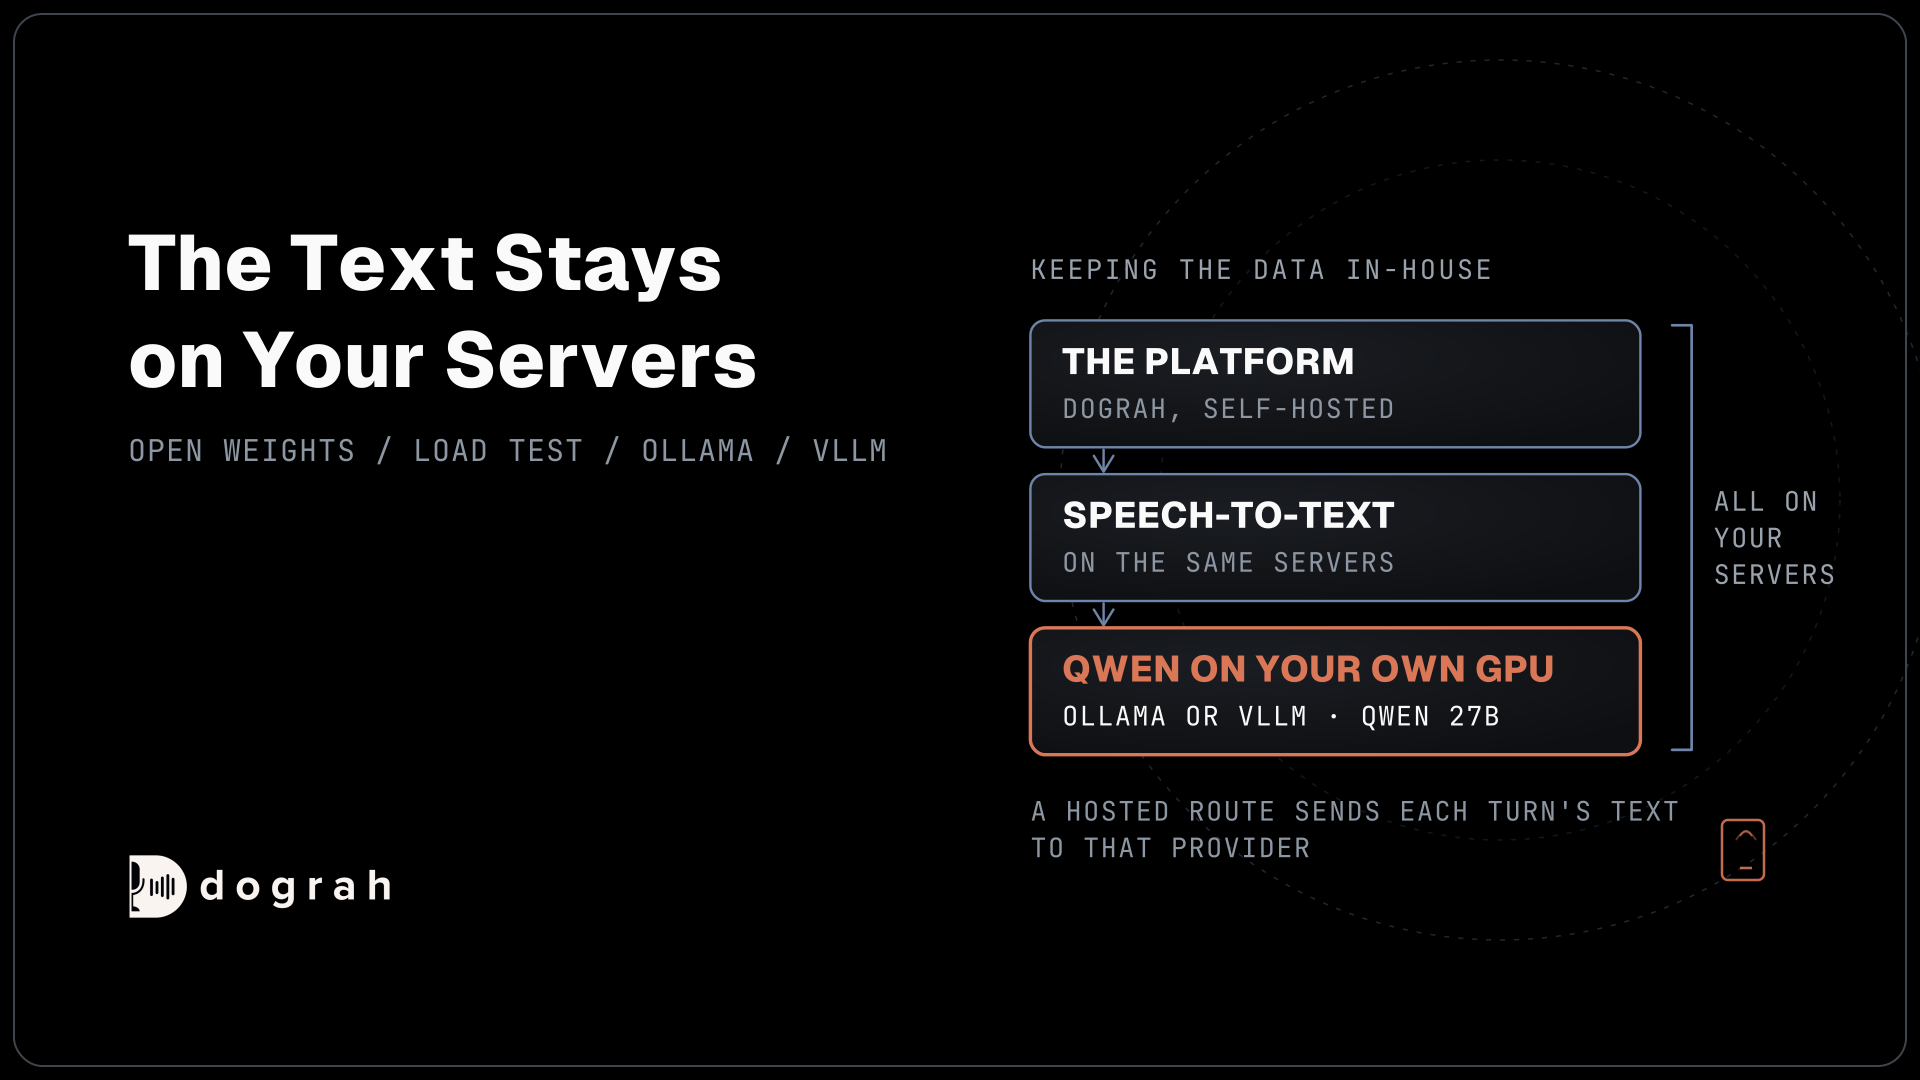
Qwen API Pricing in 2026: What a Voice Agent Call Costs
Qwen API pricing for voice agents: Alibaba Cloud Model Studio's list prices for each Qwen model, one 5-minute phone call priced on each, what context caching saves, the break-even between the hosted API and open weights on a rented GPU, and how Qwen runs in Dograh.
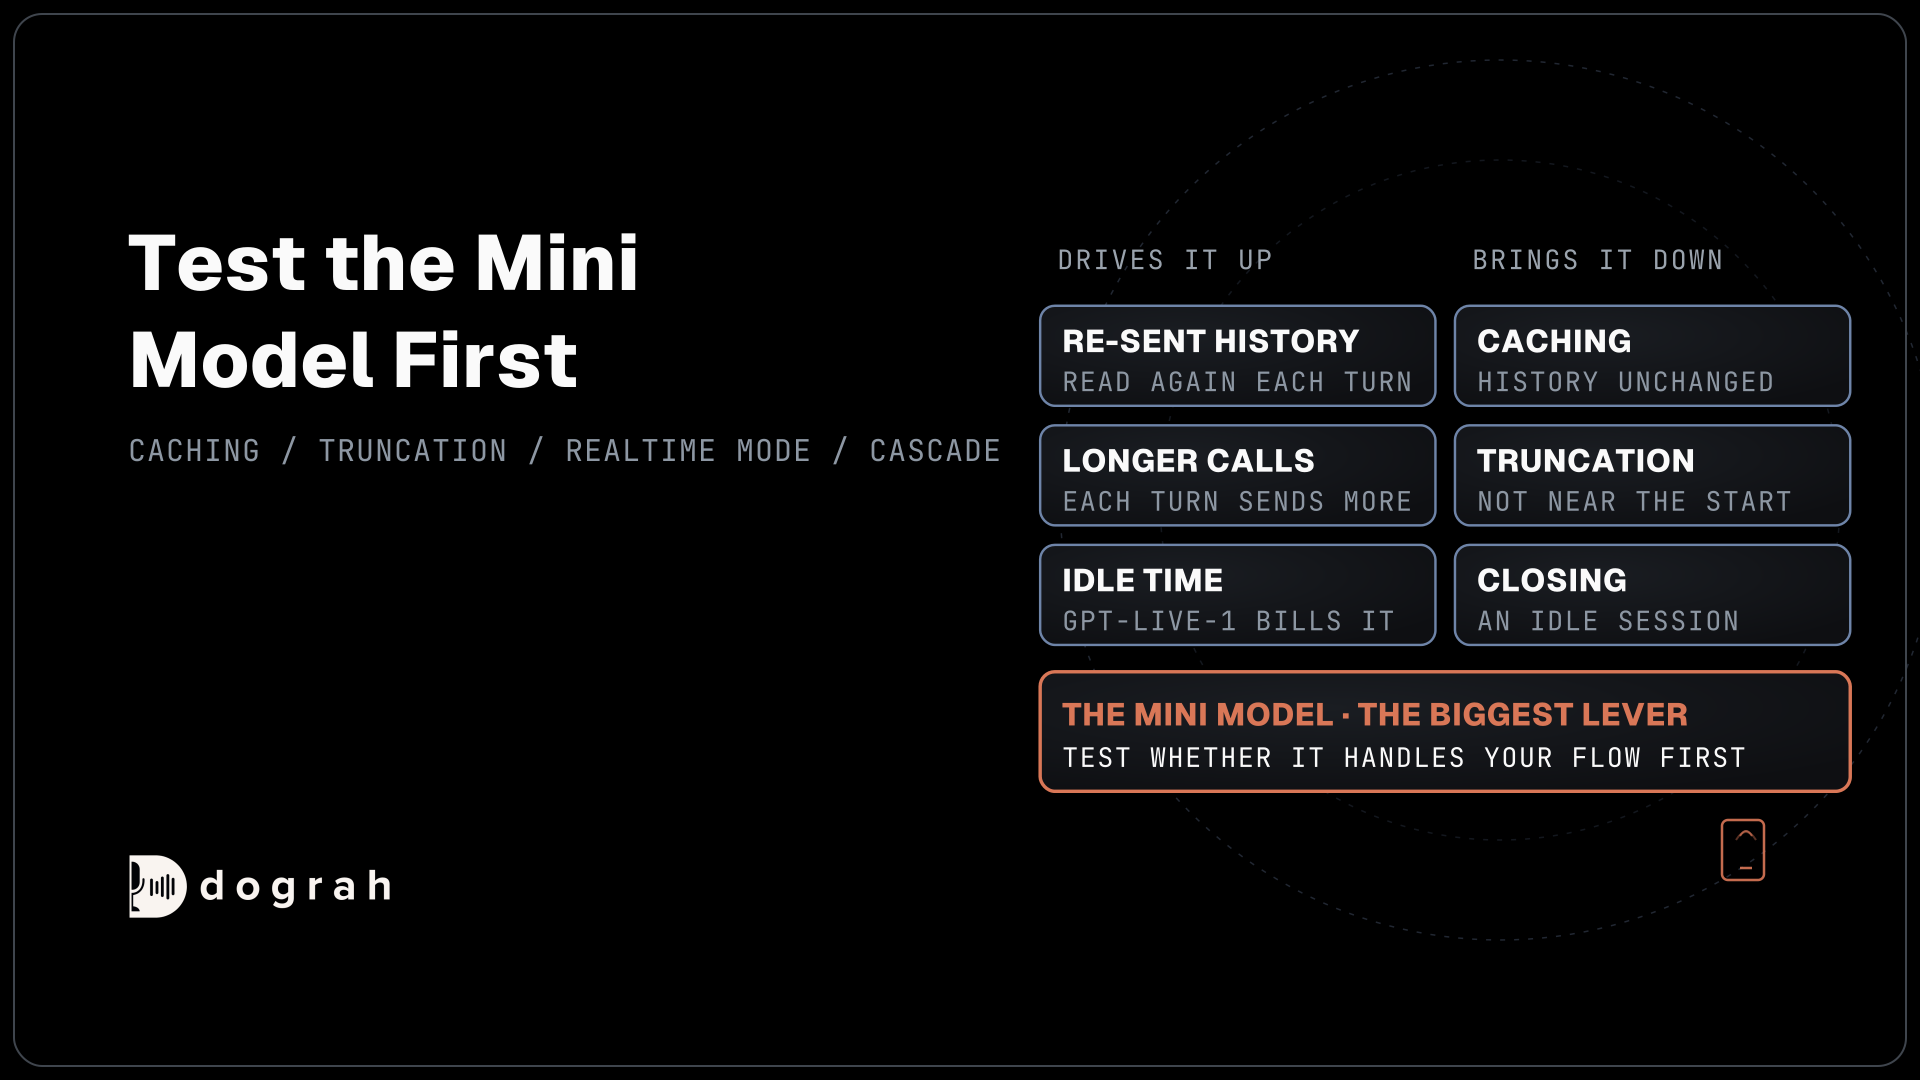
OpenAI Realtime API Pricing in 2026: Cost per Call Minute
OpenAI Realtime API pricing for phone agents: audio and text token prices, how many tokens a minute of speech makes, one 5-minute call worked out line by line as an example, what drives the bill up and down, and when a cascade fits better, with both run in Dograh.