
Our 5-minute example call comes to about $0.024 on Gemini 3.8 Flash, priced at $0.75 per million input tokens and $3.75 per million output until December 31, and roughly double from January 1, 2027. Dograh, the open-source AI voice agent platform we build, runs Gemini on your own Google key, either self-hosted or on Dograh Cloud.
Key Takeaways
- A phone prompt never reaches Gemini Flash's 4,096-token cache minimum.
- Gemini 3.8 Flash doubles in price on January 1, 2027.
- Dograh's default gemini-3.5-flash now bills at Gemini 3.6 Flash rates.
This post is part of our guide to LLM API pricing for voice agents, which prices the same 5-minute call across Claude, Gemini, Grok, Qwen and OpenAI. Below, we price it on each Gemini model, then use Dograh to plan around Google's dated price steps.
Google's prices for each Gemini model
Google charges per million tokens on its paid Standard tier, and several Gemini prices change on a set date. The figures below are Google's Gemini API prices. Output prices there include thinking tokens, so a model that reasons before it answers bills that thinking as output.
| Model | Input | Output | Cached input | Price change |
|---|---|---|---|---|
| Gemini 4 Argon | $2 | $10 | $0.10 | $4 / $20 / $0.20 from December 1 |
| Gemini 3.8 Flash | $0.75 | $3.75 | $0.075 | $1.50 / $7.50 / $0.15 from January 1, 2027 |
| Gemini 3.6 Flash | $0.75 | $3.75 | $0.075 | $1.50 / $7.50 / $0.15 from January 1, 2027 |
| Gemini 3.5 Flash-Lite | $0.30 | $2.50 | $0.03 | None listed |
| Gemini 3.1 Flash-Lite | $0.25 text, $0.50 audio | $1.50 | $0.025 | None listed |
| Gemini 3.1 Pro Preview | $2 | $12 | $0.20 | Higher above 200,000 tokens |
A cascade agent sends text to the model, since speech-to-text has already turned the caller's words into a transcript, so the text input rate is the one that applies.
One 5-minute call on each Gemini model
The call we price is the shared example from the guide. It has 12 caller-agent exchanges and a 2,000-token prompt, made of the global prompt, the current step and the tool definitions, sent with every turn. The caller adds about 25 tokens a turn and the agent replies with about 50, so across the call the model reads 29,250 input tokens and writes 600.
On Gemini 3.8 Flash at today's rates, input is 29,250 x $0.75 / 1,000,000 = $0.0219 and output is 600 x $3.75 / 1,000,000 = $0.0023. The call costs $0.0242, about $0.0048 a minute. The table runs the same sum for each model, before and after its price step.
| Model | 5-minute call now | After the price step | Per minute now |
|---|---|---|---|
| Gemini 4 Argon | $0.0645 | $0.1290 from December 1 | $0.0129 |
| Gemini 3.8 Flash | $0.0242 | $0.0484 from January 1, 2027 | $0.0048 |
| Gemini 3.6 Flash | $0.0242 | $0.0484 from January 1, 2027 | $0.0048 |
| Gemini 3.5 Flash-Lite | $0.0103 | No step | $0.0021 |
| Gemini 3.1 Flash-Lite | $0.0082 | No step | $0.0016 |
| Gemini 3.1 Pro Preview | $0.0657 | No step | $0.0131 |
Flash-Lite is the low end at about a cent a call, and it holds its price into the new year. Argon and 3.1 Pro Preview cost more than six times as much, which only pays off if your flow needs their reasoning, and any thinking they do adds output tokens on top of these figures.

Open Source Alternative to Vapi / Retell
Self-hosted voice agent platform — no per-minute fees
dograh-hq/dograh
Star on GitHub
Why implicit caching misses a phone prompt
On Gemini, the list price is the price for this call. Implicit caching is on by default for Gemini 2.5 and newer models, so a repeated start of a prompt is billed at the cached rate without any setting. The catch is length. Google's caching rules set a minimum of 4,096 tokens for Gemini 4 Argon, 3.8 Flash, 3.6 Flash and 3.1 Pro Preview.
The biggest request in our call is the last turn at 2,850 tokens, so no turn qualifies and every token bills at the full rate. An agent with a much longer prompt, such as a big tool list or a long policy section, can cross the line, and its cached part then bills at a tenth of the input rate. For the Flash-Lite models, read the cached-token count in your usage data before you count on any discount.
Price steps and model routing to plan for
Google's dates matter more to a Gemini phone budget than caching does. Gemini 4 Argon doubles on December 1, and Gemini 3.8 Flash and 3.6 Flash double on January 1, 2027. A team running 10,000 of our example calls a month on 3.8 Flash would see the LLM line move from about $242 to $484.
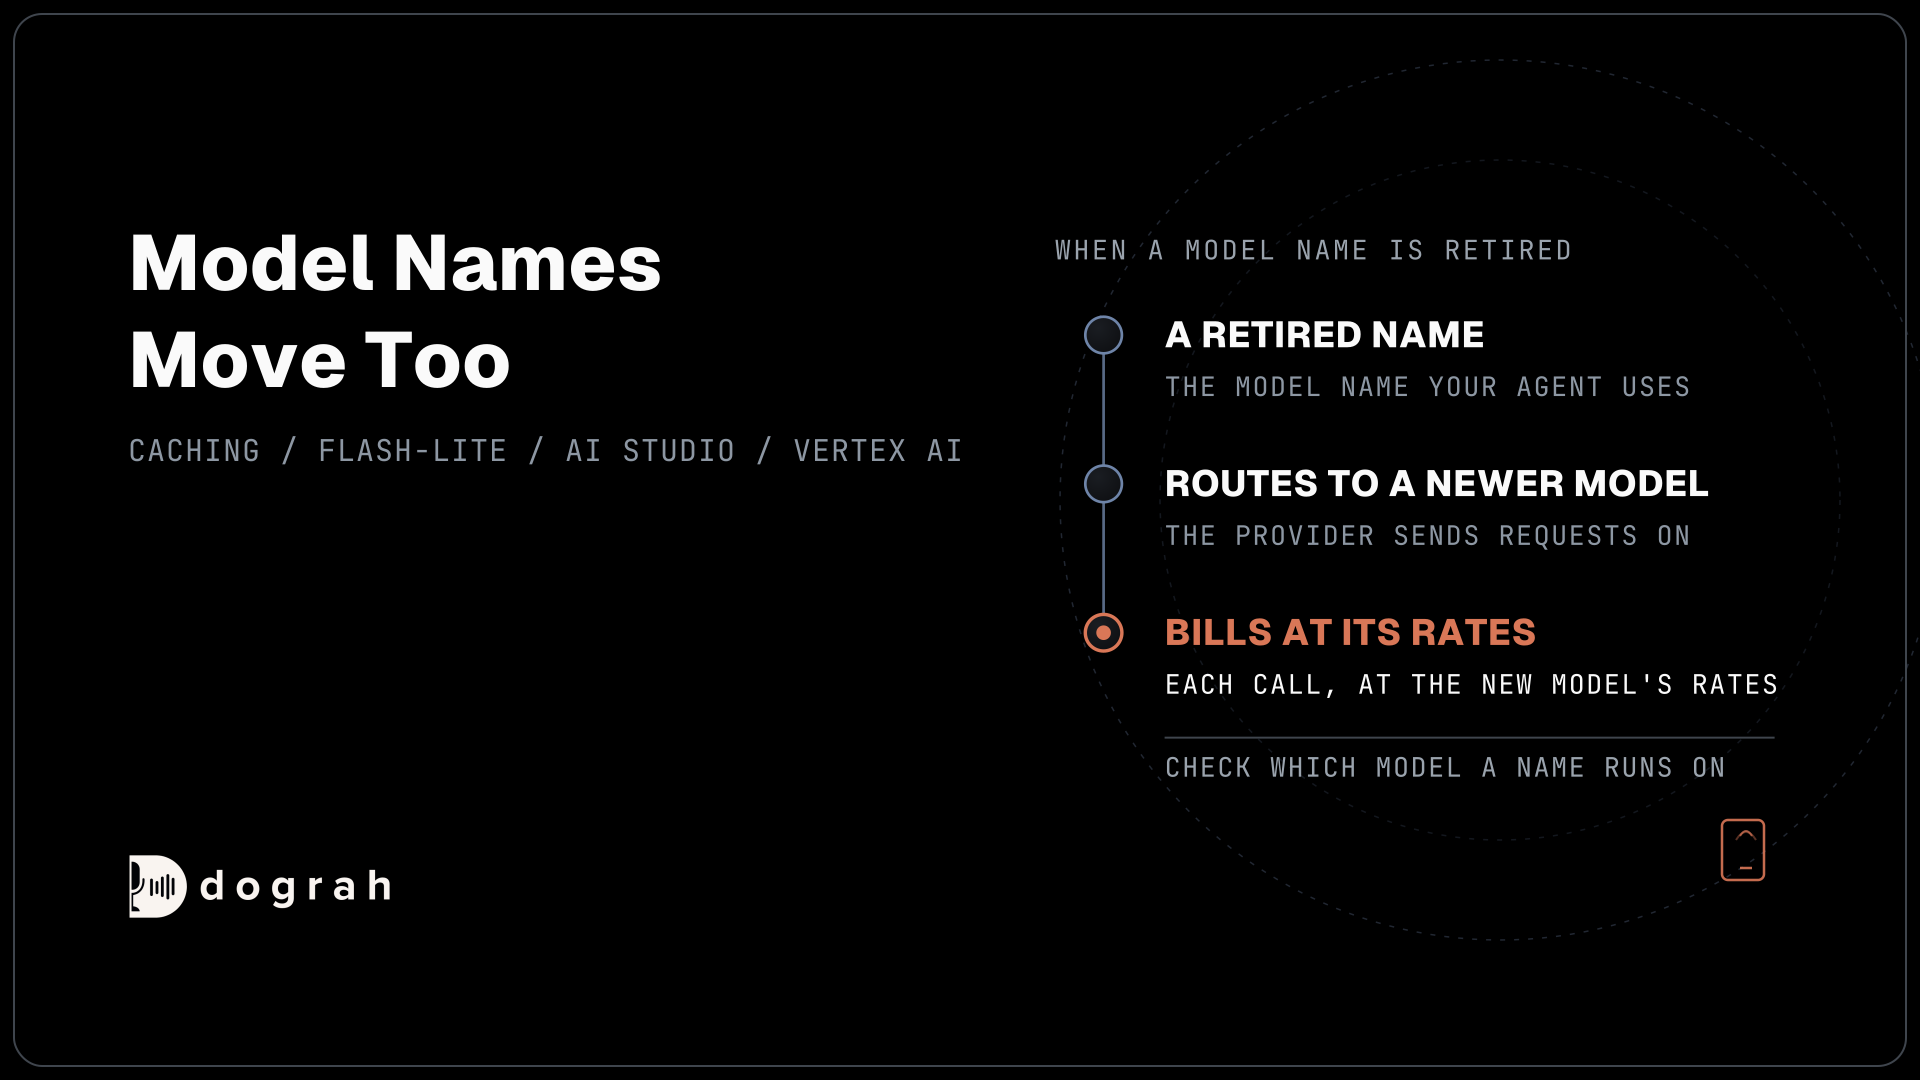
Model names move too. In AI Studio, gemini-3.5-flash is no longer offered, and its endpoint now routes requests to gemini-3.6-flash. From December 1, requests to gemini-2.5-pro route to Gemini 3.8 Flash and gemini-2.5-flash to Gemini 3.5 Flash-Lite, each billed at the new model's rates.
Dograh's default Google model is gemini-3.5-flash, so a call on the default runs on Gemini 3.6 Flash and bills at its rates, $0.0242 for our example call and $0.0484 from January 1. If the new-year price does not fit your budget, Flash-Lite keeps its rate, and the next section shows how to move one agent at a time.
Switching Gemini models per agent in Dograh
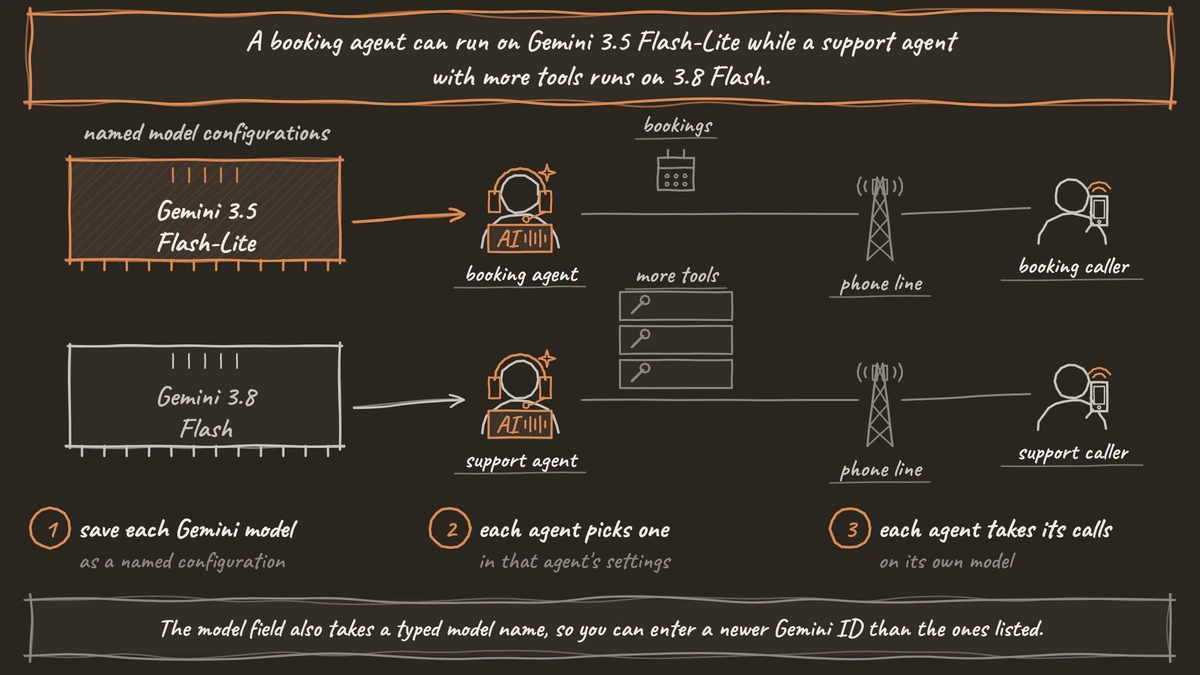
Dograh handles orchestration, the call flow, tools and telephony, and leaves the speech and language models as a separate layer you pick, Gemini included. Gemini connects through Google AI Studio or Vertex AI with your own credentials, or through OpenRouter. The model field also takes a typed model name, so you can enter a newer Gemini ID than the ones listed.
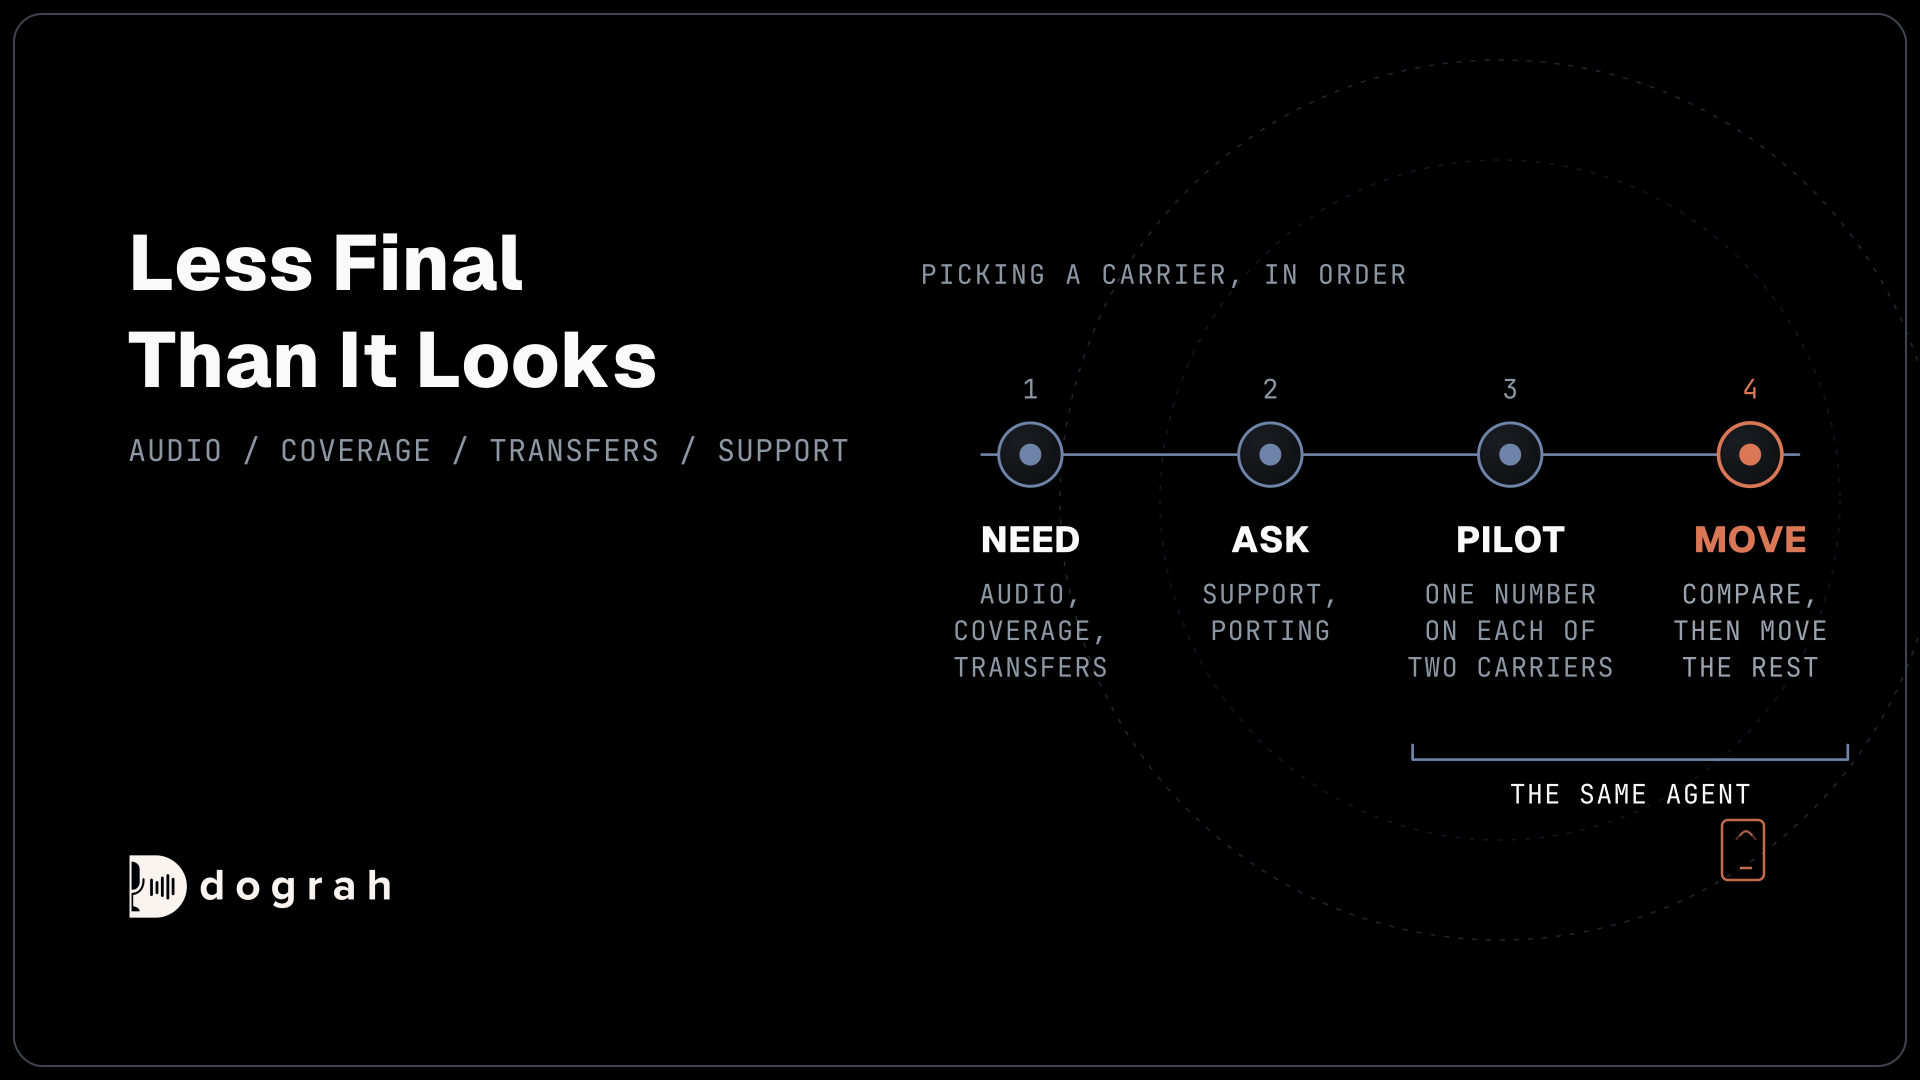
Each agent picks its model from named model configurations. A booking agent can run on Gemini 3.5 Flash-Lite while a support agent with more tools runs on 3.8 Flash. With your own LLM keys, an LLM fallback can also bring in a second model when the main one fails or gives no reply within 1.5 seconds, the default wait.
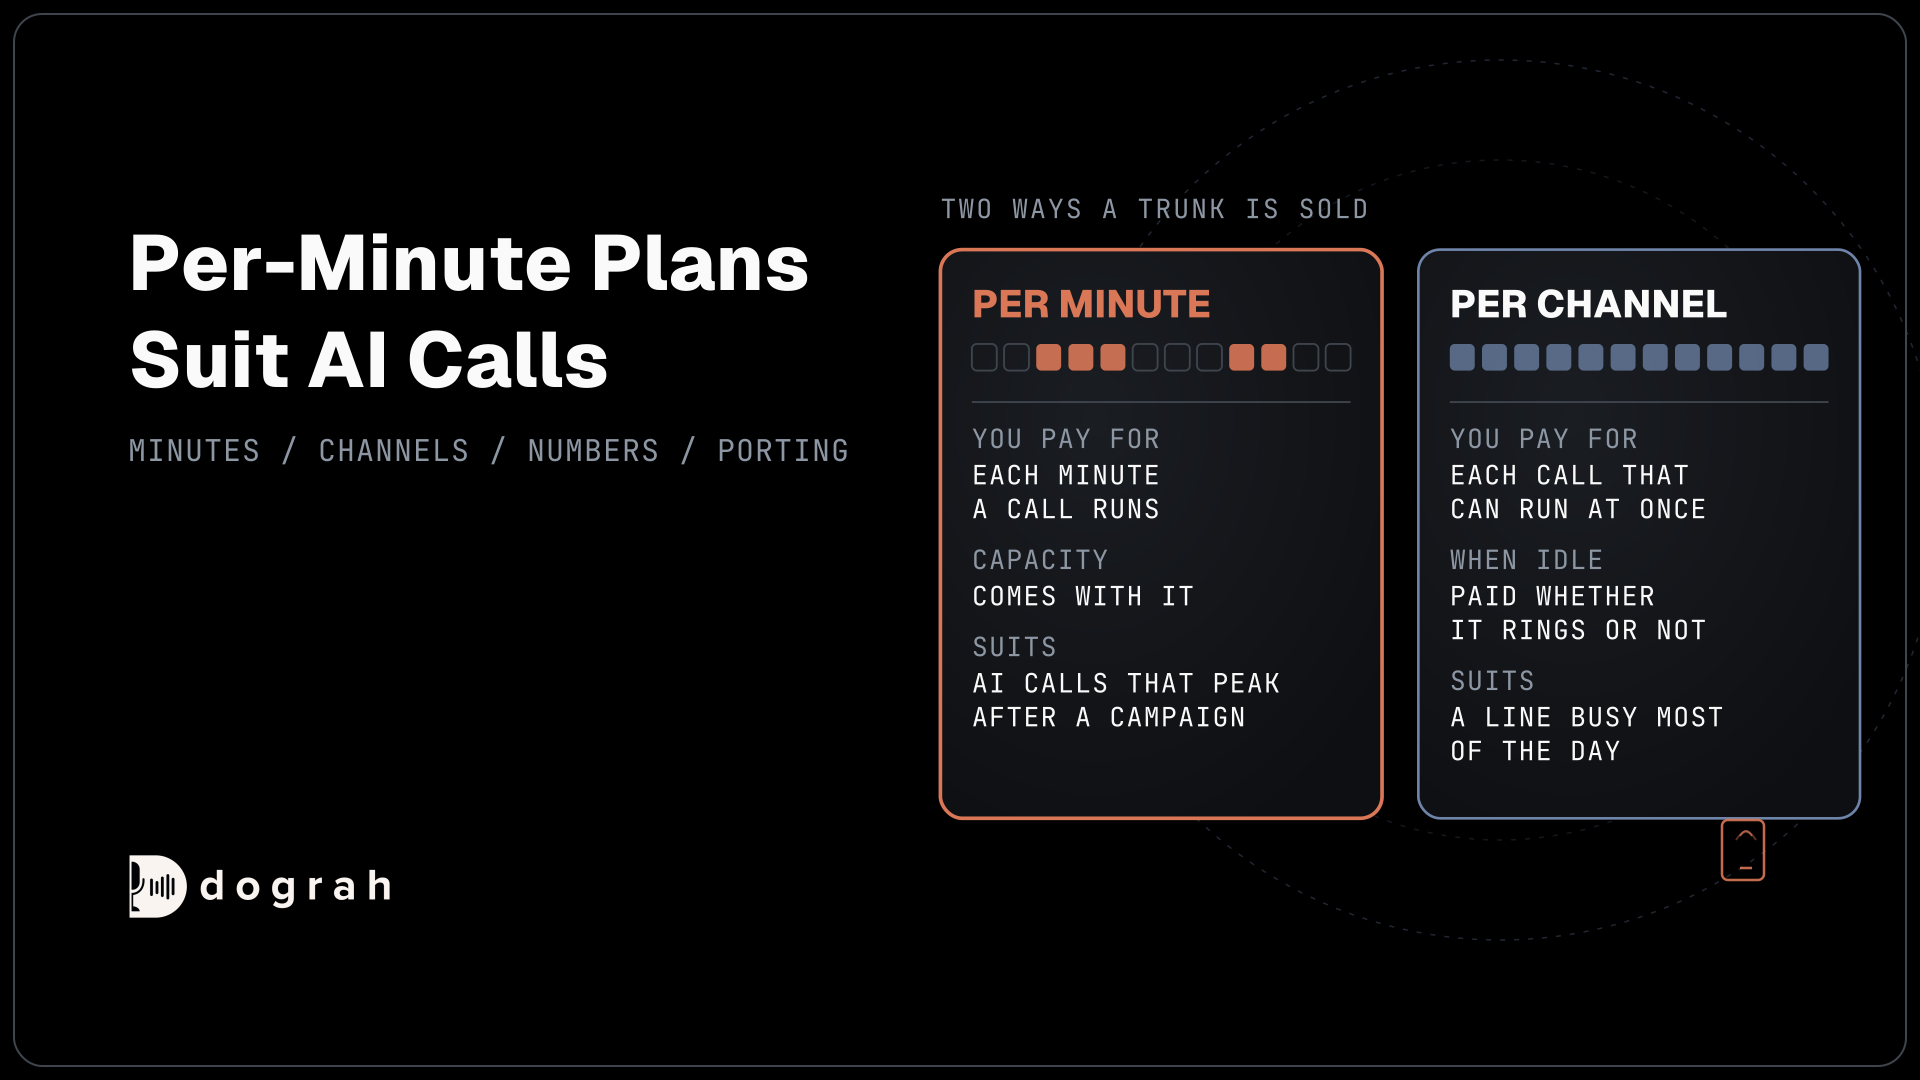
Self-hosted Dograh has no per-minute platform fee, but servers, model keys and phone minutes still cost money. Dograh Cloud charges a 1¢-a-minute platform fee. Google bills the Gemini tokens to your own account at the rates above. If you are weighing Gemini's speech-to-speech model instead, our comparison of realtime voice APIs for phone agents covers Gemini Live's per-minute audio prices, and our guide on how to choose an LLM for voice agents covers the tests to run before you switch.
Join the Dograh Community
Dograh is an OSS alternative to Vapi. Join our Slack community for queries, releases, best practices & community interactions.
Glossary
- Implicit caching
- Google's automatic discount for a request that starts the same way as a recent one. It needs no setting, but on Gemini 3.8 Flash and 4 Argon it only applies to prompts of at least 4,096 tokens, which a short phone prompt does not reach.
- Thinking tokens
- Tokens a model writes while it reasons before answering. Google bills them at the output rate, so a Gemini model that thinks on every turn costs more than the spoken reply alone suggests.
- Model routing
- When a provider sends requests for a retired model name to a newer model. Google routes gemini-3.5-flash to gemini-3.6-flash, and the call is billed at the newer model's price.
- Price step
- A list price change set for a known date. Gemini 3.8 Flash and 3.6 Flash double on January 1, 2027, so a budget built on today's rate needs a second line from that date.