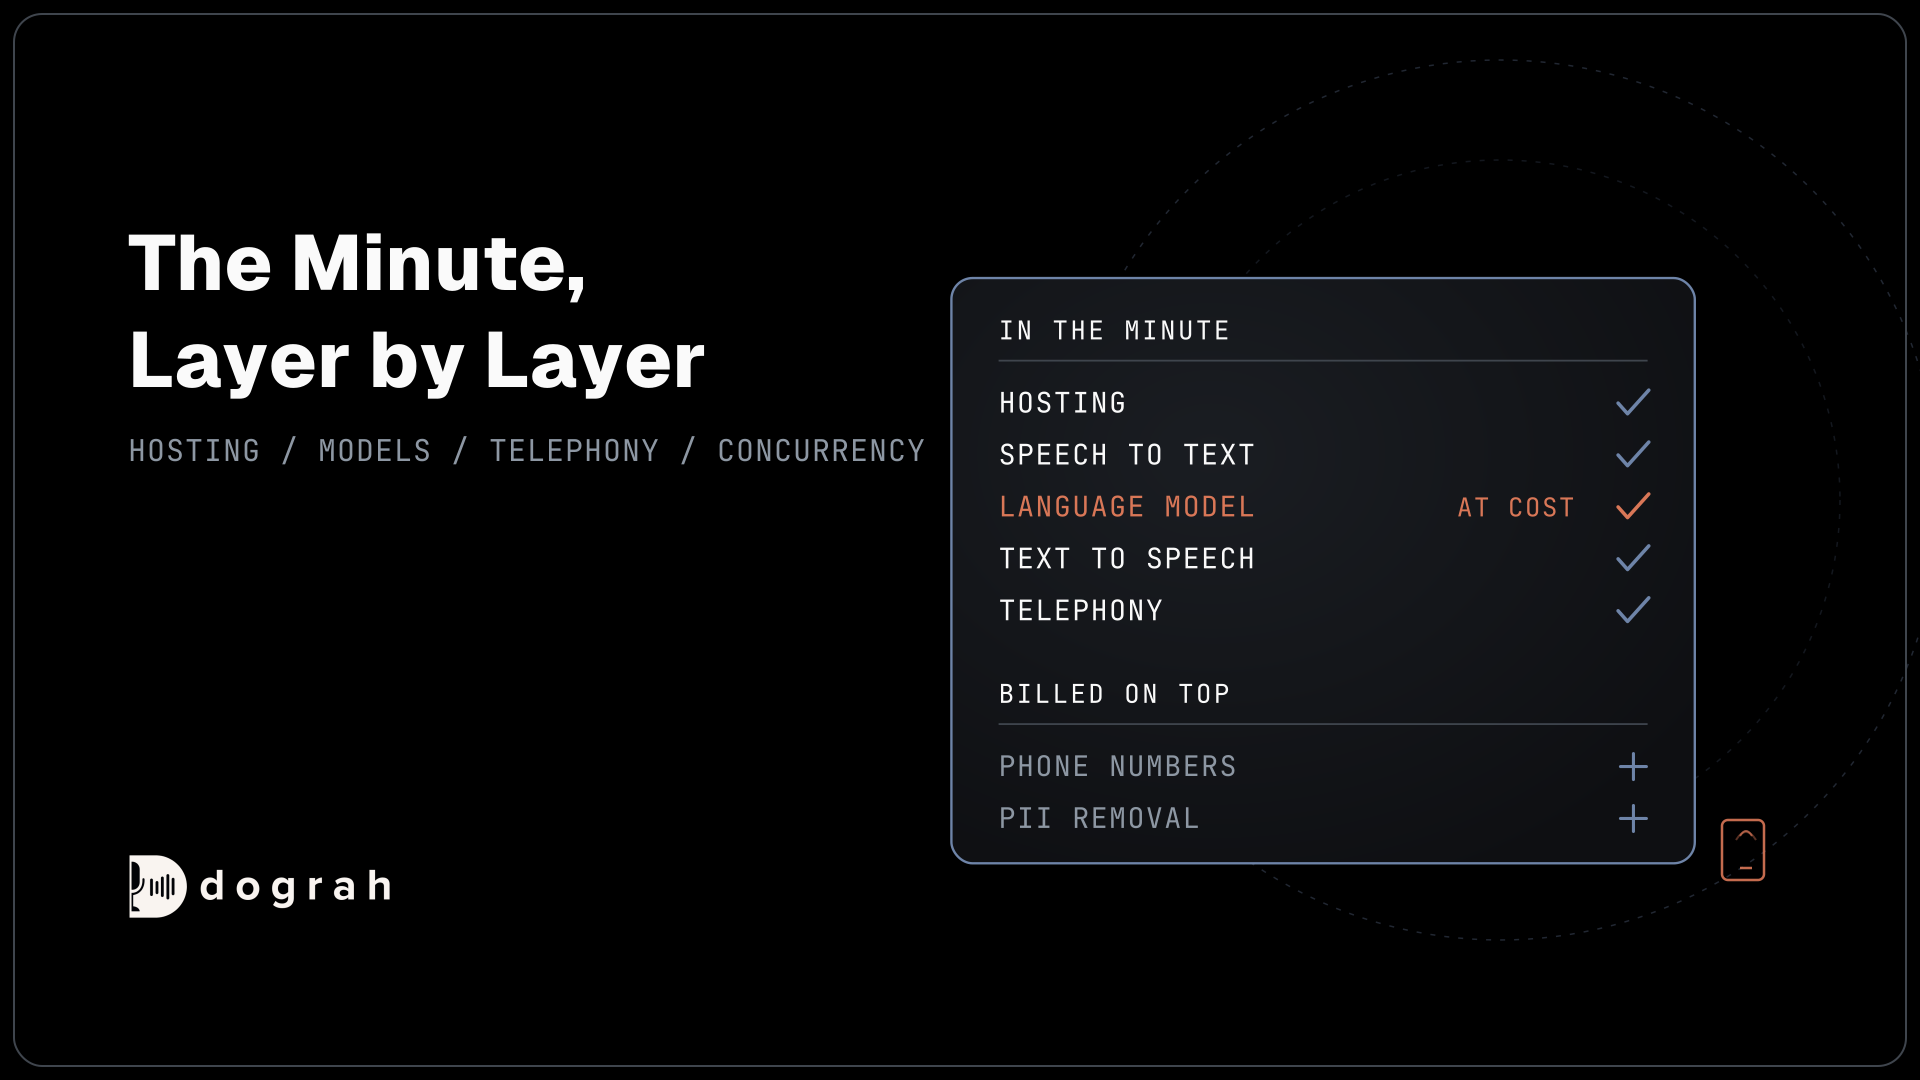

Smallest AI prices its Atoms voice agents by the minute, in layers. On Pay as you go a minute costs $0.09 to $0.21 depending on the models, with $10 in free credits. Enterprise starts from $0.05 a minute. Smallest's own voice and transcription models also run in Dograh, an open-source platform you can self-host or run on Dograh Cloud.
Key Takeaways
- A Pay as you go minute runs $0.09 to $0.21, set by your models.
- Pay as you go includes 20 concurrent calls, with no add-on for more.
- HIPAA zero data retention is a $1,000-a-month add-on on Pay as you go.
This post is part of our guide to Smallest AI alternatives. The guide's cost section makes one point. Smallest AI prices an agent minute in layers. Here we take each layer in turn, then the charges outside the minute, a worked minute and when the pricing fits.
Two plans: Pay as you go and Enterprise
Smallest AI sells two plans for voice agents, and only Pay as you go has public per-line prices. Smallest's pricing page starts Pay as you go with $10 in free credits, no commitments and no long-term contract. You pay for the minutes you use, and agents are unlimited on both plans. Purchases are non-refundable by default, and payments are processed in the US, so some international cards need international payments turned on.
Enterprise is priced per customer, and its minute starts from $0.05. Most of its lines read "Custom". What it adds is mostly infrastructure and support, including dedicated infrastructure with a 99.99% uptime SLA, forward deployed engineers, priority and prompt engineering support, custom integrations and branding, SSO and SOC 2 compliance support, and on-premise deployment. Electron, Smallest's own small language model, is available only here.
The minute, layer by layer
A minute's price depends on how the agent is built, and Smallest lists the layers one by one. A cascading agent adds up hosting, speech to text, the language model, text to speech and telephony. A speech-to-speech agent replaces the middle three with one model, so it is hosting, the speech-to-speech model and telephony.
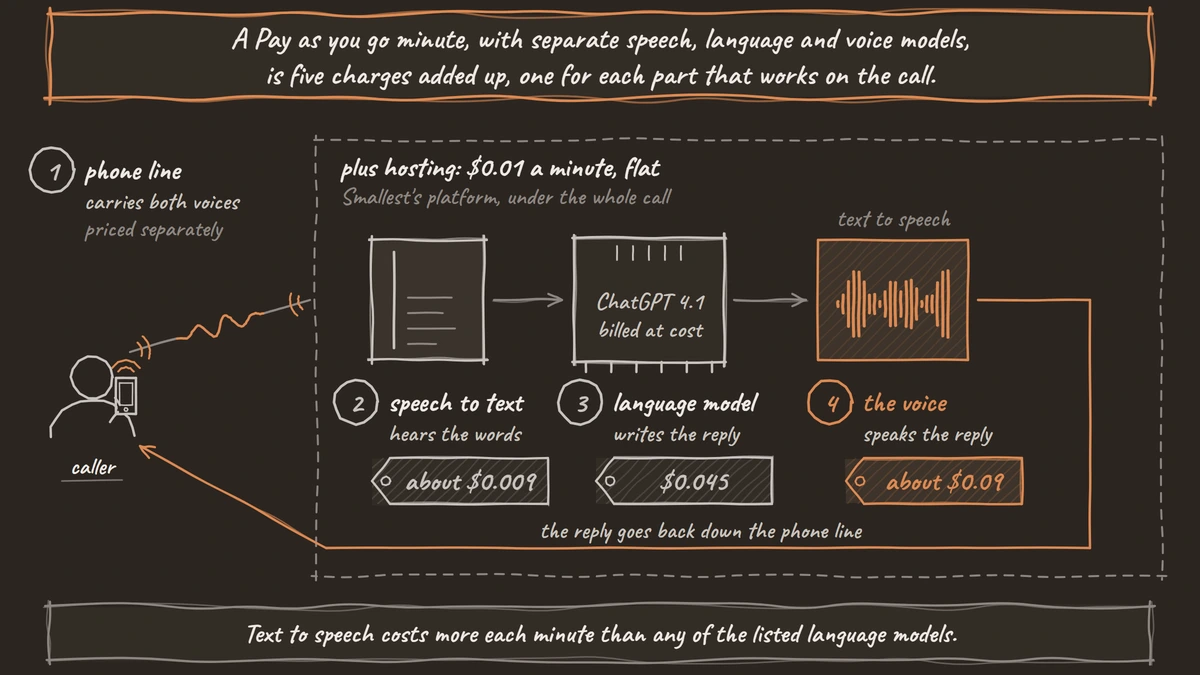
On Pay as you go, hosting is a flat $0.01 a minute and speech to text about $0.009. The language model is billed at cost, about $0.0448 a minute for ChatGPT 4.0, $0.045 for ChatGPT 4.1 and $0.056 for ChatGPT 5.2. Text to speech is about $0.09 a minute. A speech-to-speech model is also billed at cost, about $0.10 a minute for ChatGPT Realtime or about $0.02 for ChatGPT Realtime Mini.
Text to speech is the biggest single layer in a cascading minute, larger than any of the listed language models. The language model line is passed through "at cost", so the model you pick moves the total, from about $0.0448 to $0.056 among the listed ones.
Smallest also sells its models directly, outside Atoms. Its model pricing page lists Lightning V3.1 at about $0.175 per 10,000 characters, Lightning V3.1 Pro at about $0.195, and Pulse realtime speech to text at about $0.004 a minute.

Open Source Alternative to Vapi / Retell
Self-hosted voice agent platform — no per-minute fees
dograh-hq/dograh
Star on GitHub
What sits outside the minute
Several charges sit beside the per-minute price, and two of them shape the plan you need. Phone numbers rented from Smallest cost $10 a number a month. You can bring your own telephony provider instead, billed at cost by that provider. The knowledge base costs $3 per GB per user to store and $2 per 1,000 queries. PII removal, which strips sensitive details, adds $0.01 a minute. Text messages are listed as coming soon on Pay as you go and $0.005 a message on Enterprise, and advanced campaigns are coming soon.
Concurrency is the first plan-shaping line. Pay as you go includes 20 concurrent calls, and there is no option to buy more, so a 21st call at the same moment needs an Enterprise plan with custom concurrency. When every slot is busy, an inbound call rings for about 30 seconds and then disconnects.
HIPAA is the second. Smallest offers HIPAA zero data retention as a $1,000-a-month add-on on pay-as-you-go and includes it on Enterprise. It signs a BAA on Enterprise plans with zero data retention turned on.
A worked minute
Here is one cascading minute on Pay as you go, using GPT-4.1, worked out by our own arithmetic from the layer prices above.
| Layer | Price per minute |
|---|---|
| Hosting | $0.01 |
| Speech to text | about $0.009 |
| Language model (ChatGPT 4.1) | $0.045 |
| Text to speech | about $0.09 |
| Total before telephony | about $0.154 |
With ChatGPT 5.2 the same minute is about $0.165, and a speech-to-speech agent on ChatGPT Realtime Mini is about $0.03 before telephony. Smallest's own headline range for a Pay as you go minute is $0.09 to $0.21, and Enterprise starts from $0.05.
When Smallest's pricing fits
Smallest's pricing suits teams that want to start small and keep everything with one vendor. There is no monthly platform fee or minimum on Pay as you go, so a pilot pays only for its minutes, after the $10 in credits. The language model is passed through at cost, and the speech models are Smallest's own, so voice, transcription and hosting arrive on one bill. Twenty concurrent calls cover many small support lines and campaigns from the first day.
The plan stops fitting at the edges. A line that needs more than 20 calls at once, on-premise deployment, an uptime SLA or SSO moves you to Enterprise, where the price comes from a sales conversation. Our Dograh vs Smallest AI comparison covers the features behind those lines, row by row.
Running Smallest's models in Dograh
Smallest's models are not tied to Atoms. They also run inside Dograh, an open-source, self-hostable AI voice agent platform, as built-in providers. On Dograh's Models page, Smallest AI can supply the voice, with lightning_v3.1 or lightning_v3.1_pro, and the transcription, with Pulse, using your own Smallest API key. The voice settings cover each field. Use of those models is billed by Smallest, on your own account.
This suits teams that like Smallest's voices but want to run the platform themselves, with their own carrier and call records. Our post on the open-source alternative to Smallest AI covers what changes when you own the platform.
Join the Dograh Community
Dograh is an OSS alternative to Vapi. Join our Slack community for queries, releases, best practices & community interactions.
Glossary
- Hosting fee
- Smallest's per-minute charge for running the call on its platform: $0.01 a minute, a flat rate, on Pay as you go. The models and the phone line are priced as separate layers on top.
- Cascading architecture
- An agent built from separate speech-to-text, language and text-to-speech models. On Smallest, its minute is hosting plus those three layers plus telephony.
- Speech-to-speech model
- One model that hears the caller and answers in speech, replacing the three cascading layers. On Smallest it is billed at cost, for example about $0.02 a minute for ChatGPT Realtime Mini.
- Concurrency
- How many calls run at the same moment. Smallest's Pay as you go includes 20, with no option to add more. Enterprise sets a custom number.