
OpenAI's Whisper API costs $0.006 a minute with no hardware, but it does not stream, so it suits recordings. Whisper on your own GPU wins when the card stays busy or the audio must stay in your network. Dograh, the open-source AI voice agent platform, runs self-hosted Whisper. You can self-host it or run it on Dograh Cloud.
Key Takeaways
- OpenAI's Whisper API does not stream, so it suits recordings over live calls.
- One rented L4 for a month costs about 71,800 Whisper API minutes.
- Only Whisper on your own servers keeps call audio inside your network.
This post is part of our guide to open-source speech-to-text models, where Whisper is the easiest open model to start with in Dograh. Here we compare OpenAI's Whisper APIs with Whisper on your own GPU on cost, speed and the limits a live call puts on each.
OpenAI's two Whisper APIs
OpenAI sells Whisper in two forms, and only one of them streams. The classic whisper-1 model costs $0.006 a minute. It takes a finished file of up to 25 MB, and it does not support streaming.
OpenAI's speech-to-text guide says as much. For audio that is "still arriving from a microphone, call, or media stream", it points you to realtime transcription. That is where gpt-realtime-whisper sits, at $0.017 a minute, and it only works through OpenAI's Realtime transcription sessions, not the usual transcription endpoint.
So the batch API is a good fit for recordings after the call, such as a second, more careful transcript for review. A live phone agent needs the words while the caller is still on the line, which is where the cost and speed questions below come in.
Whisper on your own GPU
The Whisper model itself is free to run, under the MIT licence, on any GPU you have. The turbo model has 809 million parameters and needs about 6 GB of GPU memory in OpenAI's original code, while large-v3 has 1,550 million and needs about 10 GB. Its model card notes that turbo cut the decoder from 32 layers to 4, which is where its speed comes from.
Most teams run it through faster-whisper, which uses less memory and runs faster at the same accuracy. Our comparison of Whisper vs Parakeet vs Voxtral gives faster-whisper's own memory figures beside the other two models.
One habit needs testing before real callers hear it. The large-v3-turbo model card warns that Whisper can produce text that was never spoken, a hallucination. Play silence, coughs and hold music through it, and check the agent does not reply to words nobody said.
When the API wins on cost, and when your GPU does
This table sets the Whisper routes side by side.
| Route | Price | Streams on a live call | Where the audio goes | In Dograh |
|---|---|---|---|---|
| Dograh with self-hosted Whisper (Speaches) | Your GPU, from $0.59 an hour for a secure L4 | Finished sentences, one request each | Stays on your servers | Local Models (Speaches) |
| Hosted Whisper on Hugging Face | Billed by Hugging Face | Finished sentences | Hugging Face's inference providers | Hugging Face provider, openai/whisper-large-v3-turbo by default |
OpenAI Whisper API (whisper-1) | $0.006 a minute | No | OpenAI | Use it for recordings after the call |
OpenAI gpt-realtime-whisper | $0.017 a minute | Yes, through Realtime sessions | OpenAI | Use it in your own apps |
Here is our arithmetic. RunPod lists an L4 at $0.59 an hour on its secure cloud. Kept on for a 730-hour month, that is about $431. At the Whisper API's $0.006 a minute, $431 buys about 71,800 minutes, close to 1,200 hours of audio. At the live rate of $0.017, it buys about 25,300 minutes.
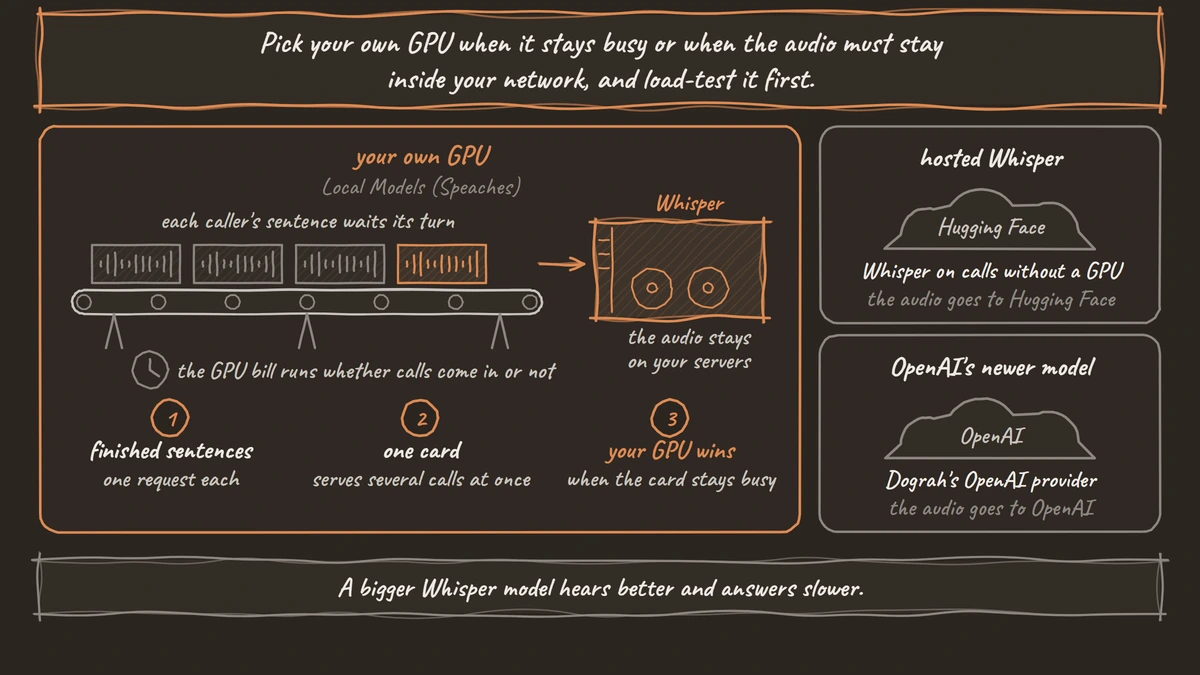
The GPU only wins if it stays busy. One card can serve several calls at once, but each caller's sentence waits its turn, so how many calls it carries depends on the model size and your own hardware. Load-test that number before you decide, and remember the GPU bill runs whether calls come in or not.
The API wins at low volume and for recordings, and it suits a team that does not want to run GPUs. Your own GPU wins when the card stays busy, for example because it already sits beside your language model, or when the audio cannot leave your network. Self-hosted Dograh has no per-minute platform fee, but servers, model keys and phone minutes still cost money. Dograh Cloud charges a 1¢-a-minute platform fee.

Open Source Alternative to Vapi / Retell
Self-hosted voice agent platform — no per-minute fees
dograh-hq/dograh
Star on GitHub
Speed and live-call limits
Whisper was built to read audio in 30-second windows, and its turbo card says it does not do real-time transcription out of the box. That shapes how it runs on a phone call.
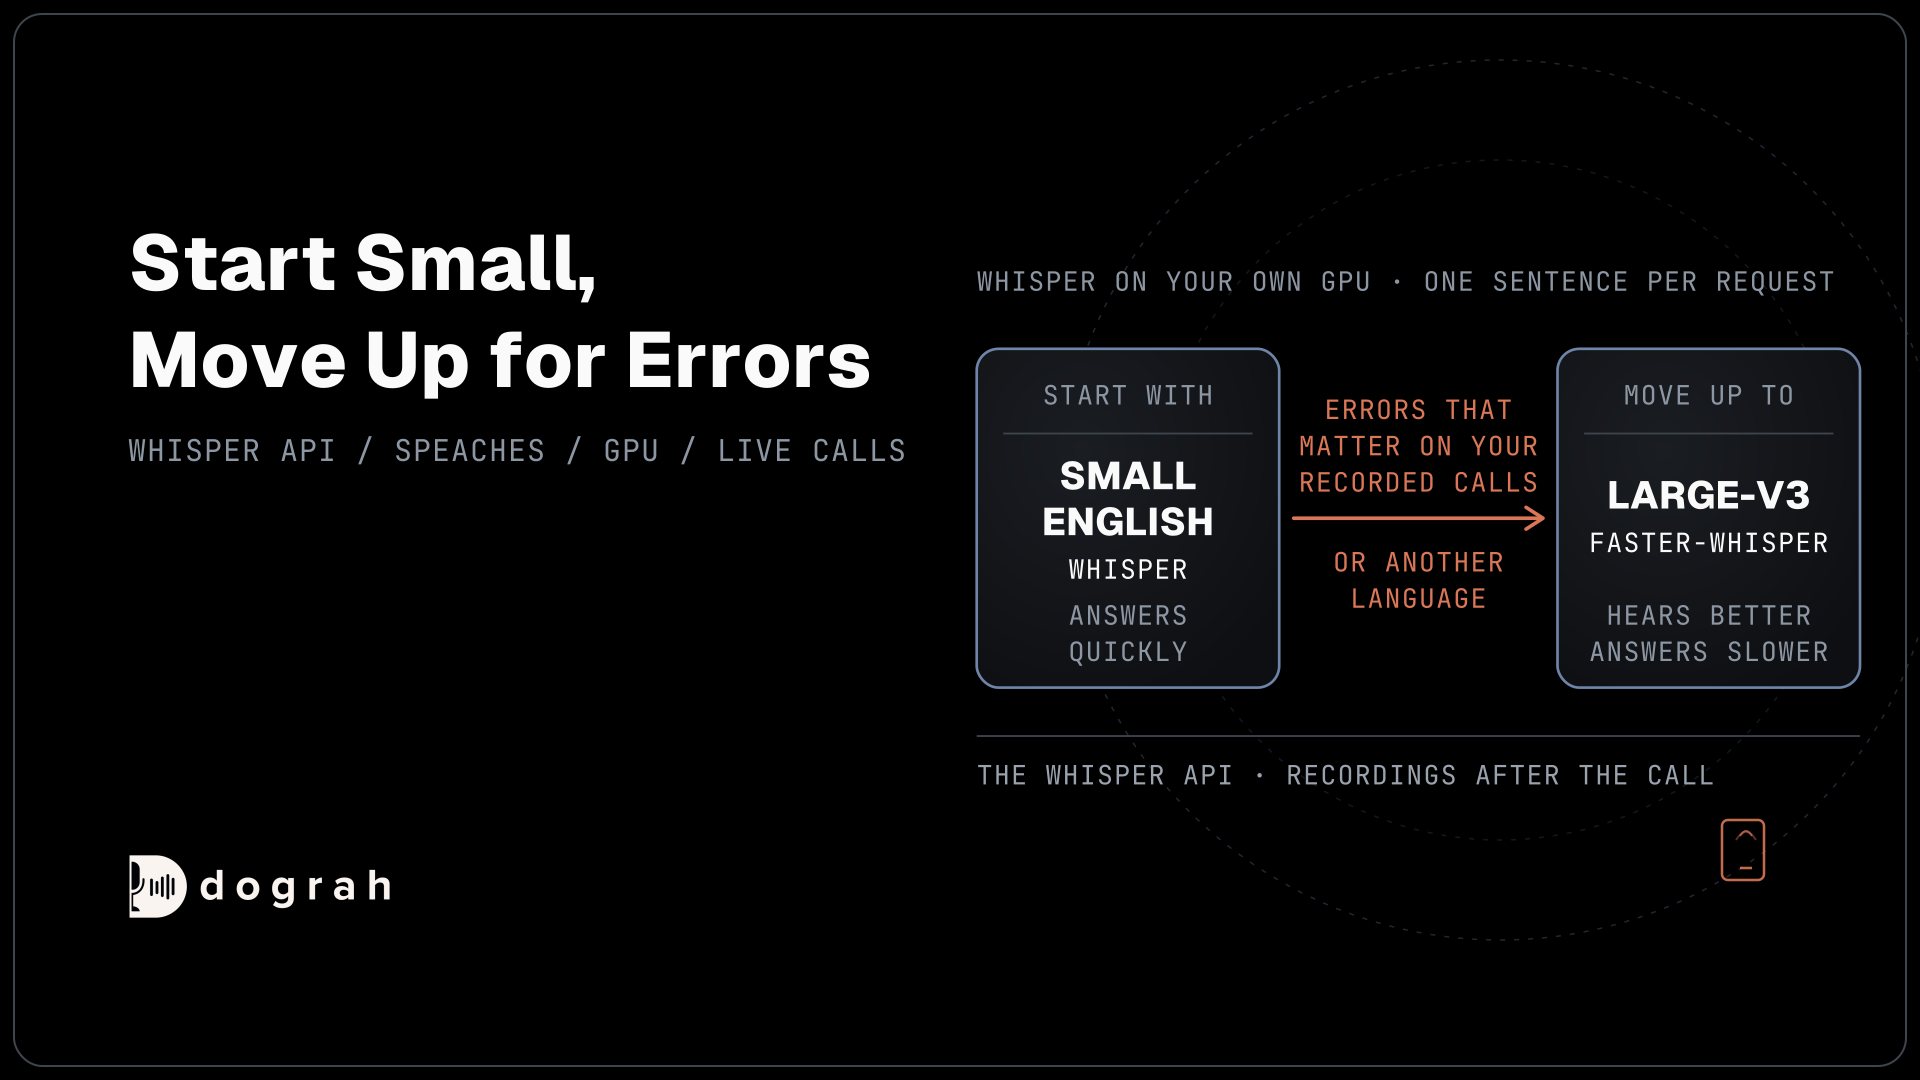
With the Local Models (Speaches) option, Dograh waits for the caller to pause, then sends that finished speech segment to your Whisper server as one request. The caller hears nothing until the text comes back and the agent replies, so the speed that matters is how long one sentence takes on your card. A bigger Whisper model hears better and answers slower.
Start with the default Systran/faster-distil-whisper-small.en, a distilled English-only model that answers quickly, and move to Systran/faster-whisper-large-v3 only when your recorded calls show errors that matter, or you need another language. Our tutorial on running faster-whisper locally covers the setup, and each call's trace shows the speech-to-text time for every turn.
If you need words while the caller is still talking, a streaming provider is the better fit. Our list of the best speech-to-text APIs for voice agents compares the hosted ones that stream.
Running either one in Dograh
Dograh gives you two Whisper routes for live calls. For self-hosting, add a Local Models (Speaches) provider pointing at your Speaches server, which runs Whisper with faster-whisper. For a hosted Whisper with no GPU, choose the Hugging Face provider, whose default model is openai/whisper-large-v3-turbo.
Dograh's OpenAI provider runs gpt-4o-transcribe, OpenAI's newer transcription model. If you also want OpenAI's batch Whisper, send it your call recordings after the call from your own code.
Only Whisper on your own servers keeps the caller's audio inside your network. The hosted routes send it to Hugging Face's providers or to OpenAI. On a self-hosted install, also set ENABLE_TELEMETRY=false and remove POSTHOG_API_KEY to switch off anonymous usage telemetry. The Transcriber settings list every speech-to-text provider an agent can use.
Join the Dograh Community
Dograh is an OSS alternative to Vapi. Join our Slack community for queries, releases, best practices & community interactions.
Which one to pick
Pick OpenAI's Whisper API for recordings and low volume, and keep it out of the live call. Pick hosted Whisper on Hugging Face when you want Whisper on calls without a GPU. Pick your own GPU when it stays busy or when the audio must stay inside your network, and load-test it first.
Glossary
- faster-whisper
- A reimplementation of Whisper on the CTranslate2 engine that runs the same weights faster and in less memory, especially at int8. Speaches uses it to serve Whisper to Dograh.
- Realtime transcription session
- OpenAI's streaming connection for audio that is still arriving. gpt-realtime-whisper only works through it, while whisper-1 takes finished files.
- Hallucination
- Text a speech model writes that nobody said, often during silence or background noise. Whisper's turbo model card warns about it, so test silence before going live.
- Speech segment
- The stretch of speech between two pauses. Dograh sends each segment to a Whisper server as one request, so its transcription time adds to the reply.