
For a self-hosted phone agent, start with Whisper served by faster-whisper through Speaches. It connects directly to Dograh, the open-source AI voice agent platform you can self-host or run on Dograh Cloud. Parakeet TDT is the fast choice for English and European languages, and Voxtral Mini needs about 9.5 GB of GPU memory. Test both on real calls.
Key Takeaways
- The server around the model decides what your voice agent can call.
- Phone codecs hurt some speech models far more than others, so test yours.
- Parakeet fits beside a 27B language model on one card. Voxtral Mini does not.
A model that scores well on clean recordings can still mishear names on 8 kHz phone audio. We compare how Whisper, Parakeet and Voxtral reach Dograh, then their phone accuracy, speed, GPU memory, languages and licenses. For the wider field, see our guide to self-hosted voice models.
How each model reaches a voice agent
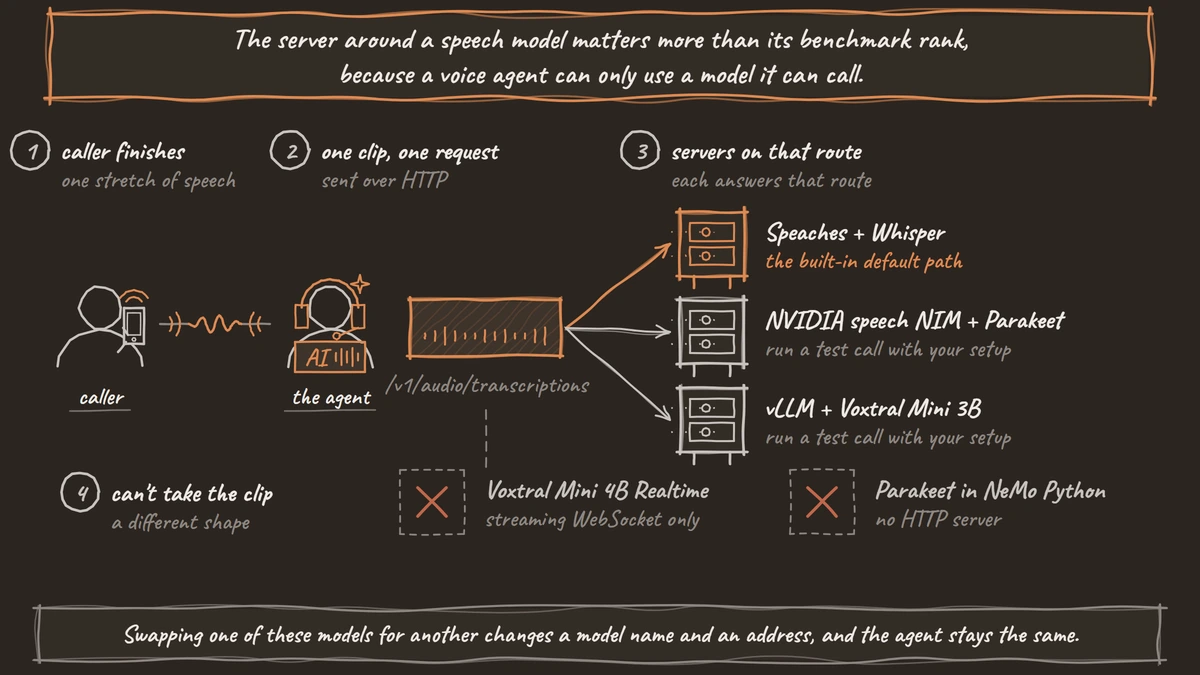
The server around a speech model matters more than its benchmark rank, because a voice agent can only use a model it can call. In Dograh, local speech-to-text runs through the Local Models (Speaches) option in Model Configurations. You give it a server address and a model name. Dograh then sends each speech segment, one finished stretch of the caller's speech, to that server as one HTTP request to /v1/audio/transcriptions, the OpenAI-compatible transcription route that OpenAI's own API defined.
Whisper is the model this path was built around. Speaches, an open-source server under the MIT license, runs Whisper models with faster-whisper and answers that route. Dograh's default model name is Systran/faster-distil-whisper-small.en, and Systran/faster-whisper-large-v3 is listed beside it. You can type any other model name your server holds.
Parakeet and Voxtral reach the same route through other servers. NVIDIA's speech NIM container serves Parakeet over HTTP, and vLLM serves Voxtral Mini 3B. Both use the transcription connection that Dograh's Local Models option works with, so run a test call with your setup before going live. With a NIM, put the NIM's own model identifier in the Model field. Dograh sends a two-letter language code such as en, while NVIDIA's docs use codes such as en-US, so check on that test call that the NIM accepts it.
Two versions need a different shape. Voxtral Mini 4B Realtime talks only over a streaming WebSocket, and Parakeet loaded in NeMo Python has no HTTP server at all. Put Parakeet behind a NIM instead, and pick the standard Voxtral Mini for this route.
The three models side by side
This table puts the facts from each model's own card next to the way it connects to Dograh.
| Model | Size and GPU memory | Languages | License | How it plugs into Dograh |
|---|---|---|---|---|
| Whisper large-v3, run by faster-whisper | 1.55B parameters. About 2.9 GB in int8, from faster-whisper's large-v2 test | 99 | MIT | Local Models (Speaches), the built-in default path |
| Parakeet TDT 0.6B v3 | 0.6B parameters. Roughly 2 GB for its English sibling v2 | 25 European | CC-BY-4.0 | NVIDIA speech NIM on the same route. Test call first |
| Voxtral Mini 3B | About 9.5 GB in bf16 | 8 | Apache-2.0 | vLLM on the same route. Test call first |
Dograh handles the call flow, tools and telephony, and the speech models in this table sit in their own layer above it. Swapping one of these models for another changes a model name and an address, and the agent stays the same.
Accuracy on phone audio
Benchmark accuracy is measured on clean recordings, while most phone calls still reach the agent as 8 kHz audio. A browser test call runs at 16 kHz, the most Dograh's pipeline uses, so a model can sound fine in your browser and still mishear names on a real line. How big that gap is depends on the speech model and the phone path.
The WildASR benchmark from Boson AI shows why you test rather than assume. It played the same English recordings through phone codecs. Whisper Large V3 went from a 4.2% word error rate on clean audio to 4.8% through G.711, the codec most landlines use. Qwen2-Audio went from 5.8% to 48.3% on the same test. One model barely moved, and the other became unusable.
WildASR did not test Parakeet or Voxtral, and no published test puts all three models on the same GPU with phone audio. So record 20 or 30 of your own calls, with real names, addresses and numbers, and run each candidate on them. Our post on live vs recorded speech-to-text explains why a model built for recorded files behaves differently on a live call.

Open Source Alternative to Vapi / Retell
Self-hosted voice agent platform — no per-minute fees
dograh-hq/dograh
Star on GitHub
Speed and GPU memory
The speed that matters on a call is how long one finished sentence takes to come back as text, because the agent cannot answer before that. Leaderboard speed figures run long batches on large datacenter GPUs. They show which model is efficient, while the delay your caller hears depends on your own card.
Memory decides what fits on one machine. faster-whisper's own benchmark ran Whisper large-v2 on 13 minutes of audio in 4,525 MB at 16-bit and in 2,926 MB at int8, with the int8 run slightly faster. Its authors report up to four times the speed of the original Whisper code at the same accuracy. Dograh's default distil-whisper small English model is far lighter again.
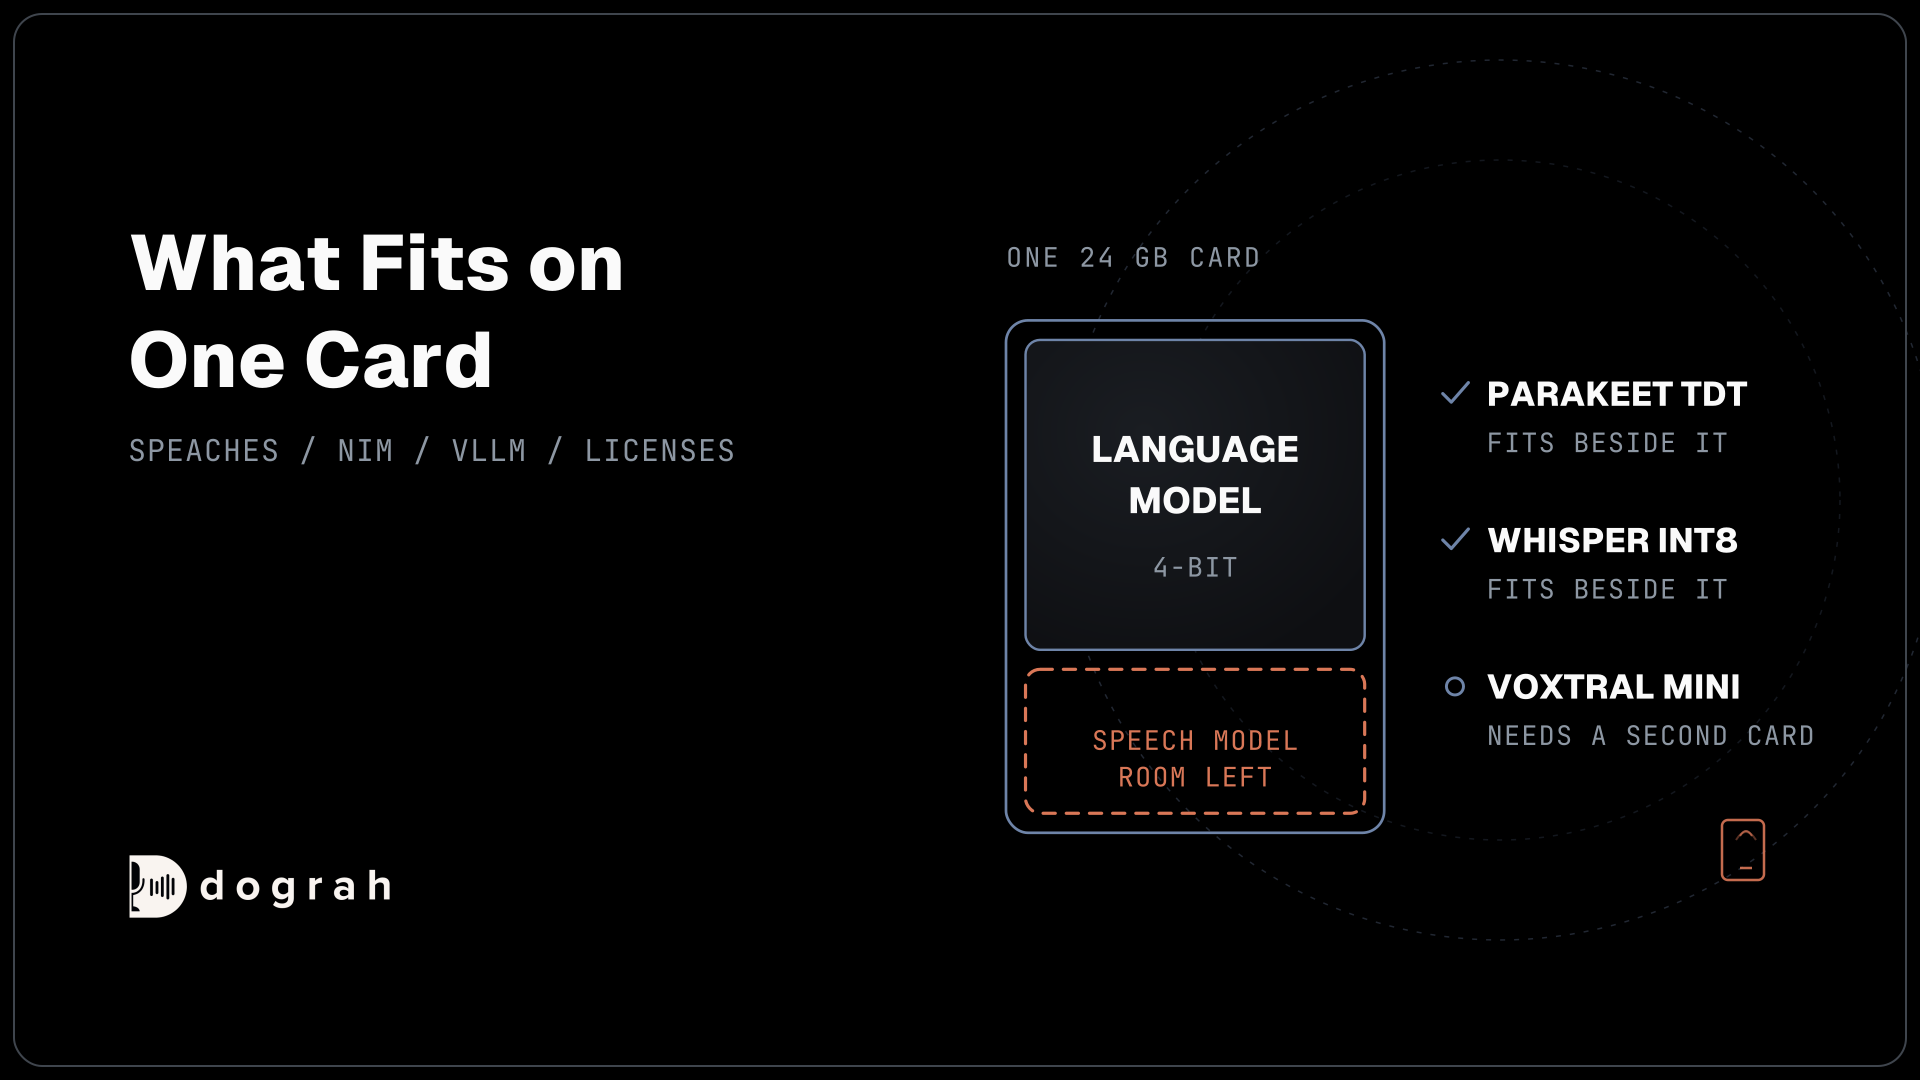
Parakeet TDT 0.6B v2 loads in roughly 2 GB. Voxtral Mini's model card asks for about 9.5 GB of GPU memory in bf16. The pillar's stack puts a 4-bit 27B language model on a 24 GB card, which leaves about 4.2 GiB. Parakeet or an int8 Whisper fits in that space. Voxtral Mini needs a second card or a bigger one.
Languages and licenses
Language needs often settle the choice before speed does. Whisper covers 99 languages. The Parakeet TDT 0.6B v3 model card lists 25 European languages, and its v2 sibling is English only. Voxtral Mini covers 8, including English, Spanish, French, Hindi and German.
In Dograh, set the Language field to the caller's two-letter code, such as en or es. The default small Whisper model is English only, so pick a multilingual Whisper model such as Systran/faster-whisper-large-v3 for other languages.
Licenses differ in one way that matters for a product. Whisper is MIT and Voxtral Mini is Apache-2.0, so you can ship either with no credit line. Parakeet is CC-BY-4.0, which allows commercial use but requires attribution to NVIDIA wherever you ship it. A NIM container comes with NVIDIA's own license terms on top of the model's, so read those before you deploy.
Join the Dograh Community
Dograh is an OSS alternative to Vapi. Join our Slack community for queries, releases, best practices & community interactions.
Which model to start with
Start with Whisper through Speaches, because it is the path Dograh ships with. Keep the default distil-whisper small English model until your own recorded calls show errors that matter, then move to large-v3. Our tutorial on how to run faster-whisper locally for a voice agent covers the setup end to end.
Move to Parakeet when your calls are in English or European languages and you need the memory for a large language model on the same card. Serve it through NVIDIA's speech NIM and make the test call before real callers arrive. NVIDIA's newer streaming and offline models are covered in what Nemotron 3.5 Transcribe means for voice agents.
Pick Voxtral Mini when you have a card with room to spare and your languages are on its list.
One setting is worth changing whichever model you run. A self-hosted Dograh install sends anonymous usage telemetry by default, and setting ENABLE_TELEMETRY=false and removing POSTHOG_API_KEY switches it off.
Glossary
- OpenAI-compatible transcription route
- The /v1/audio/transcriptions request shape that OpenAI's API defined and many open servers copy, such as Speaches, vLLM and NVIDIA's speech NIM. Dograh's Local Models option speaks this route, so any server that answers it can be tried.
- Speech segment
- One finished stretch of the caller's speech, cut where they pause. Dograh sends each segment to a local speech server as one request, so the time to transcribe it adds directly to the agent's reply time.
- G.711
- The standard codec for landline and much of mobile phone audio, sampled at 8 kHz. It strips the high frequencies speech models learn from, which is why some models lose far more accuracy on calls than on clean recordings.
- int8
- A quantization format that stores a model's weights as 8-bit integers in place of 16-bit numbers. In faster-whisper's own test it took Whisper large-v2 from about 4.5 GB of GPU memory to about 2.9 GB.